
With the growing demand for data across the business world, web scraping has become immensely famous. This method helps businesses find and utilize essential information for detailed analysis. However, some web scraping challenges make this data retrieval difficult. So, it is always better to have a clear vision of those risks before you commence the process of web scraping.
This post introduces web scraping and explains how it is used. It also covers the five most common pitfalls of this process. So, let’s get started.
What is Web Scraping?
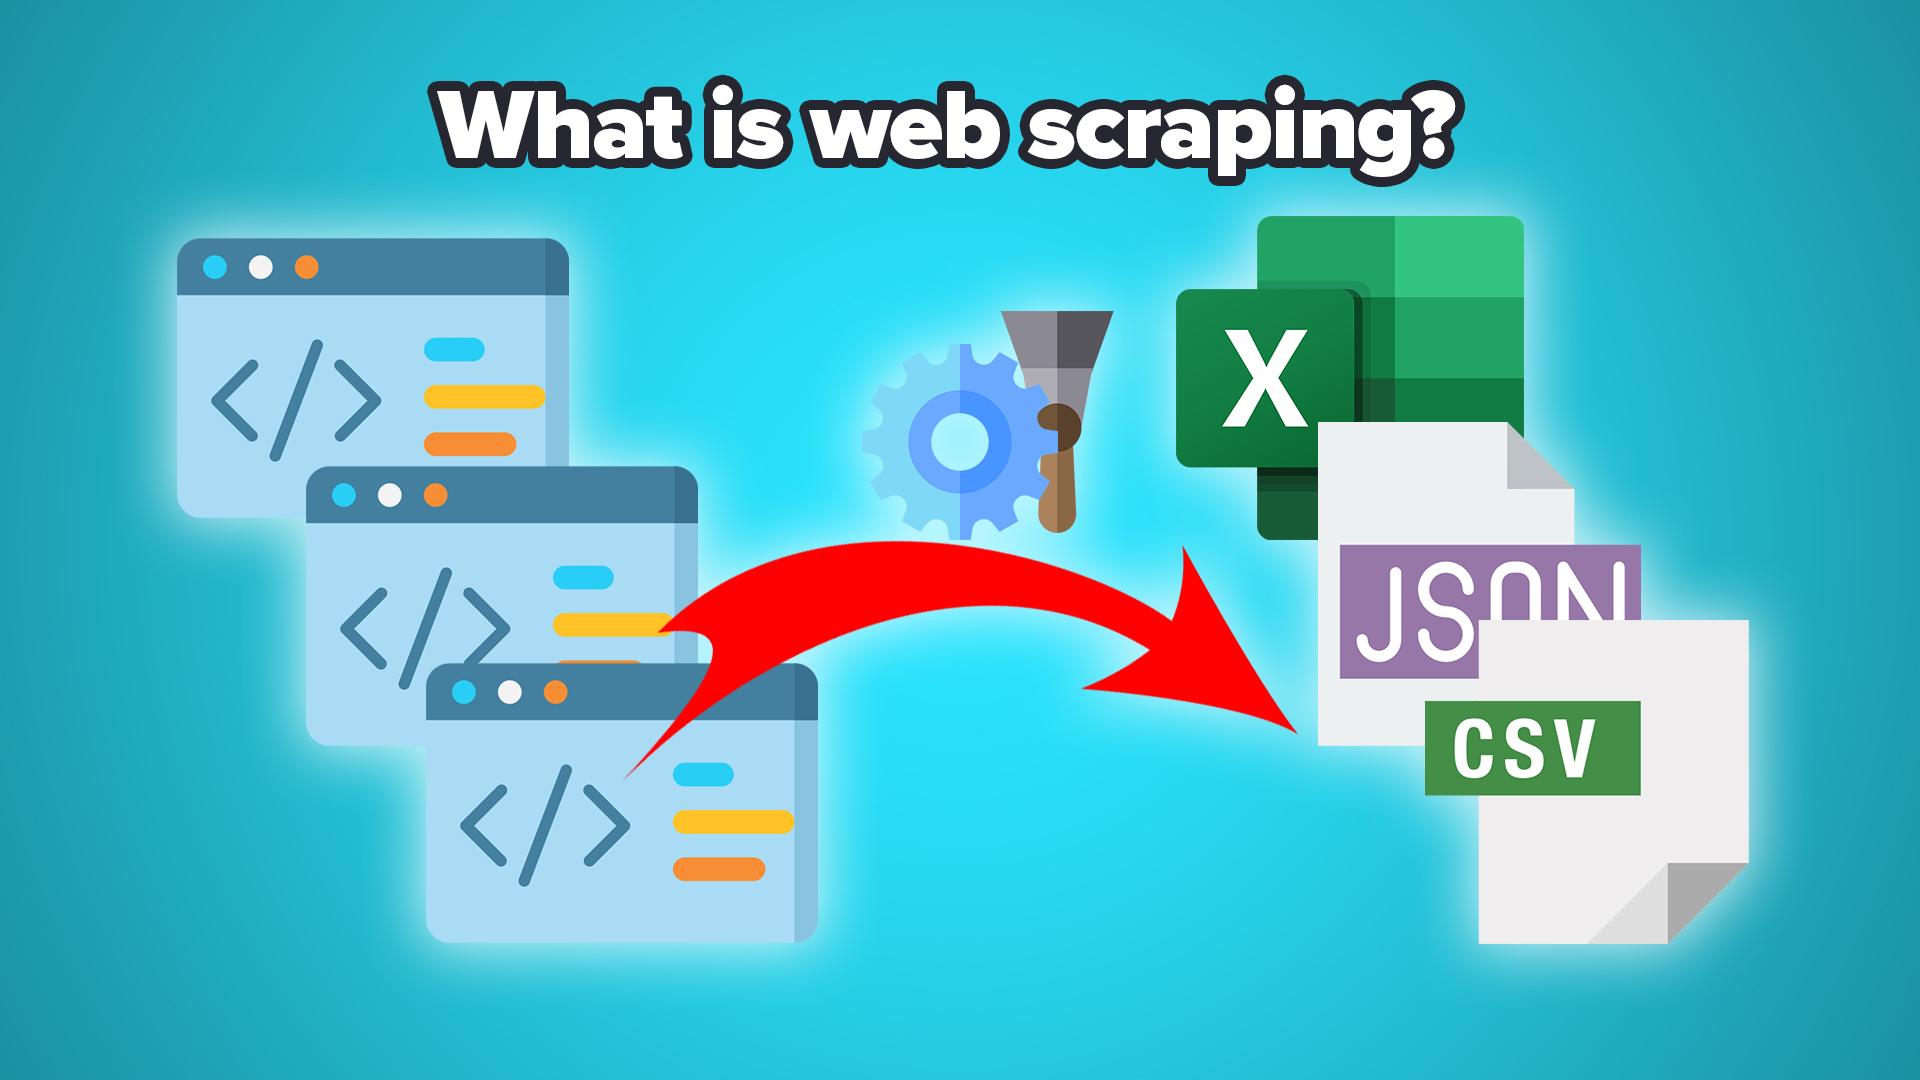
Web scraping, or data scraping, refers to the retrieval of content and data from the internet. This process uses bots (scrapers) that facilitate downloading the data from respective pages into the HTML format. Then, they save and store the extracted content in JSON or CSV files. Web scrapers are powered up by proxies to bypass site restrictions, as many websites block scraping tools to prevent them from negatively impacting their performance and speed.
Use Cases of Web Scraping
Now that we’ve covered the web scraping procedure and its functions, permit’s discover some of the maximum famous net scraping use cases:
- Market Research – Market research is the important thing source of statistics, and a great place to begin, in particular in complicated industries.
- Brand Monitoring – It is important for brands to monitor different channels to find out what people are talking about them and their products. They can use web scraping to obtain such data to gauge and track their success over time.
- Price & Product Intelligence – Web scraping technology is also used to obtain information regarding competitors’ prices and products. This practice can ensure business development and progression by automating pricing plans and market positioning.
- SEO (Search Engine Optimization) – SEO relates to a firm’s efforts to increase search engine rankings by generating content that Google can find, index, and vouch for as helpful content. Of all the moving parts of SEO, the main difficulty begins with keyword research. Web scraping tools pull information about the number of searches per month for that keyword, which devices are most common, the competitive score, etc.
5 Common Web Scraping Pitfalls
Web scrapers face several difficulties because of the barriers set by data owners to restrict non-human access to their information. Here are the most common ones:
1. Bots
Websites are given the choice of allowing scrapers bots on their sites for web scraping purposes. But some sites actually do not like automated data scraping. This is primarily because some bots can be malicious and create security issues.
2. CAPTCHA
A type of website security measure, CAPTCHA (Completely Automated Public Turing to tell Computers and Humans Apart), is created to identify bots and decline their access to websites. Logical tasks or input of characters are displayed for verification, which allows distinguishing a person from a robot. A number of CAPTCHA solvers are implemented today in bots for repeated data collection, albeit it slows down the scraping process to some extent.
3. IP Blocking
IP blocking is a common technique for stopping web scrapers from accessing a site’s data. Blocking is triggered if the server finds too many requests from the matching IP address or the search robot makes a large number of parallel requests. As a result, the site will either ban the IP fully or limit its access, breaking down the scraping process. This common pitfall may be managed if you learn how to cover your IP cope with. There are many approaches to try this and this article would possibly shed some mild on how to effectively cover an IP deal with.
4. Honeypot Traps
Site owners set honeypot traps on a page to catch scrapers. These traps are computer systems built to attract hackers and block them from accessing a site. The traps can be links that are not visible to people; however, scrapers can see them. If a scraper tries to obtain the content of a honeypot trap, it will enter a never-ending loop of requests and fail to retrieve further data.
5. Real-time Data Scraping
There is a range of instances where real-time data collection is essential, like price comparison, inventory tracking, etc. Due to the frequent change in data, scrapers need to monitor and obtain data at all times. However, as scrapers continuously monitor pages, it takes time to query and deliver data, and any variability can cause failures.
Final Thoughts
Web scraping is now omnipresent in multiple industries and areas for better business progress. However, it demands considerable planning and careful execution, particularly if you are going into it on a reasonable scale. Simply by following some key best practices like learning how to hide IP addresses, you can handle all problems that occur during web scraping.
